Serverless Inference with Pre-Loading [SoCC'24]
——Preprint at [arXiv].
Abstract
Serverless platforms increasingly host machine learning (ML) inference workflows, modeled as directed acyclic graphs (DAGs) of interdependent functions. Beyond container startup, each ML node must load libraries, model weights, and CUDA kernels before it can run. These costs accumulate along dependent DAG paths and place initialization on the end-to-end critical path. Existing systems optimize one half of this problem. DAG-agnostic pre-loading prepares nodes the request may never reach, wasting host and GPU memory. DAG-aware serving routes and scales whole functions, leaving the loading stages inside a node untouched.
This paper presents GearUp, a serverless DAG inference serving system that removes ML-node loading from the end-to-end critical path at low resource cost. GearUp profiles the loading stages of each node and schedules them inside the slack time the DAG exposes, hiding initialization behind upstream execution. It reuses initialized instances within and across requests to avoid redundant cold starts. A probabilistic, traffic-adaptive keep-alive policy sets how long idle instances are retained, balancing memory cost against cold-start risk under bursty load. On the AMBER Alert and FINRA-ML workflows with NVIDIA L40S GPUs, GearUp reduces median end-to-end latency by 64.5% and 75.9% against SMIless, for median speedups of 3.1x and 10.0x over cold execution. Integrated GPU and host memory allocation fall by up to 83.9% and 94.6% against eager pre-loading in InstaInfer. GearUp achieves 4.2x strong scaling on four workers.
——Accepted by the ACM SoCC 2024, [PDF], received the Best Paper Award.
Abstract
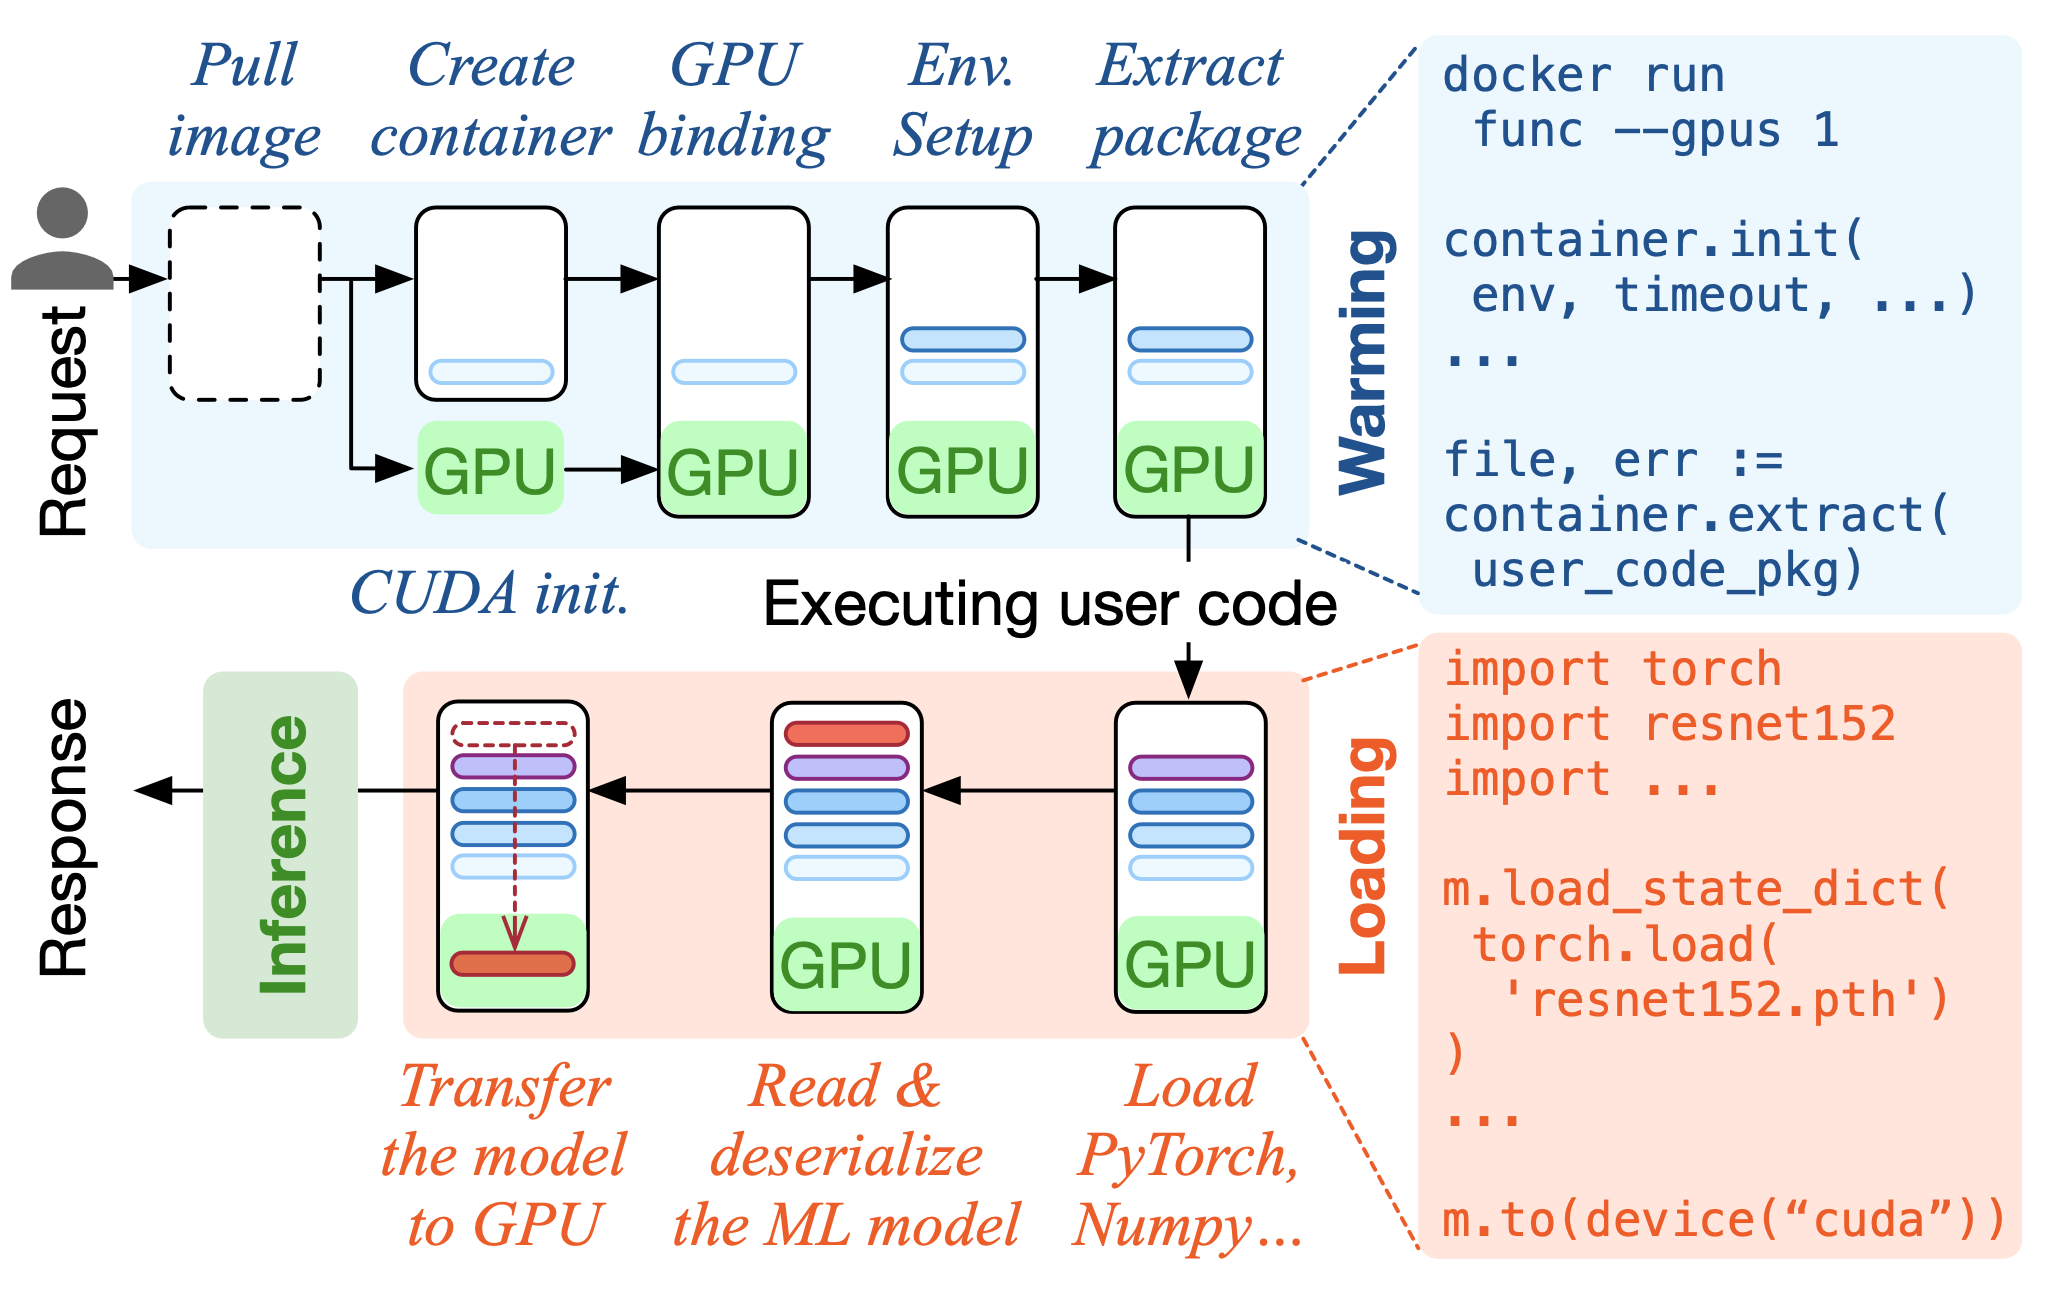
Serverless computing has rapidly prospered as a new cloud computing diagram with agile scalability, pay-as-you-go pricing, and ease-to-use features for Machine Learning (ML) inference tasks. Users package their ML code into lightweight serverless functions and execute them using containers. Unfortunately, a notorious problem, called cold-starts, hinders serverless computing from providing low-latency function executions. To mitigate cold-starts, pre-warming, which keeps containers warm predictively, has been widely accepted by academia and industry. However, pre-warming fails to eliminate the unique latency incurred by loading ML artifacts. We observed that for ML inference functions, the loading of libraries and models takes significantly more time than container warming. Consequently, pre-warming alone is not enough to mitigate the ML inference function’s cold-starts.
This paper introduces InstaInfer, an opportunistic pre-loading technique to achieve instant inference by eliminating the latency associated with loading ML artifacts, thereby achieving minimal time cost in function execution. InstaInfer fully utilizes the memory of warmed containers to pre-load the function’s libraries and model, striking a balance between maximum acceleration and resource wastage. We design InstaInfer to be transparent to providers and compatible with existing pre-warming solutions. Experiments on OpenWhisk with real-world workloads show that InstaInfer reduces up to 93\% loading latency and achieves up to 8$\times$ speedup compared to state-of-the-art pre-warming solutions.